
Data Pipeline Design for AI Apps: A Production Readiness Checklist
Summary
This article provides a production-readiness checklist for AI data pipelines, covering 8 critical dimensions: schema validation, data quality, idempotency, feature stores, lineage, ingestion scaling, secrets management, and observability. Targeting ML engineers and AI architects, it delivers actionable, expert-level guidance with real-world caveats and a clear implementation sequencing strategy.
Details
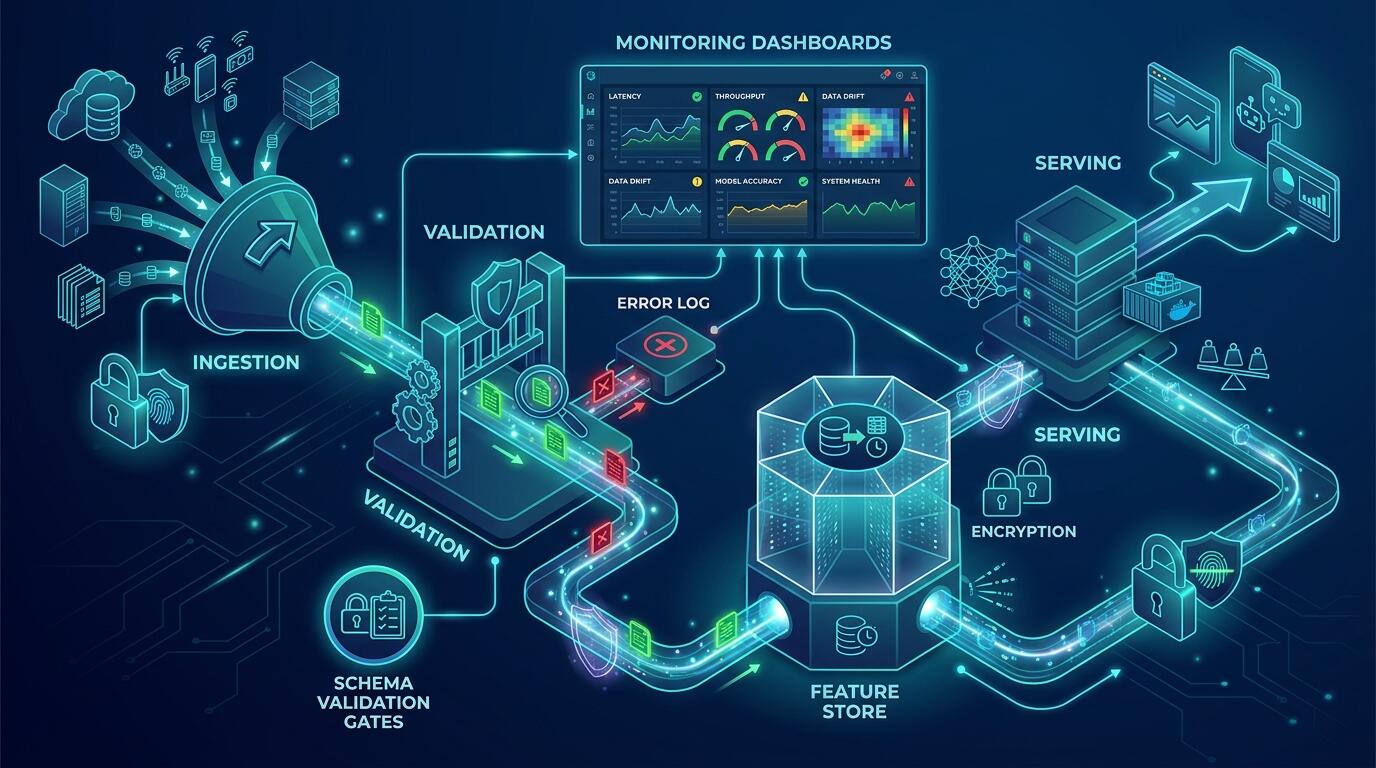 ALT: Data pipeline design checklist for AI apps ensuring production readiness from ingestion to deployment
Why Your AI App's Data Pipeline Is a Production Risk — And How to Fix It
Key Conclusion: A well-designed data pipeline is the backbone of any production-grade AI application, yet it is also the most frequently underestimated source of failure in shipped systems. This checklist distills the critical dimensions of pipeline readiness — from data ingestion and validation through to monitoring and cost governance — that separate prototypes from systems that actually hold up under real-world load. These items were selected based on patterns observed consistently across AI architecture engagements, covering the full spectrum of failure modes that emerge once a system leaves the lab.
Every AI application lives or dies by the quality and reliability of its data pipeline. A model can be state-of-the-art, the infrastructure perfectly provisioned, and the team technically strong — but if the pipeline feeding it is fragile, inconsistent, or unmonitored, the whole system degrades silently. The checklist items below were assembled from the common failure patterns we see when stepping into AI architecture engagements, distilled into actionable, verifiable criteria. Work through each one before you call your pipeline "production-ready."
The Production Readiness Checklist: Eight Dimensions Every AI Data Pipeline Must Pass
Data Source Contracts and Schema Validation
A data source contract is a formal or semi-formal agreement that defines what data a producer delivers to a consumer — including field names, types, nullability constraints, and acceptable value ranges. Without contracts, upstream changes silently corrupt downstream models. Schema drift — where a source quietly changes a field name or drops a column — is one of the most common causes of invisible degradation in production AI systems.
Schema validation should run at ingestion time, not as an afterthought. Tools such as Apache Avro, Protocol Buffers, or JSON Schema all provide mechanisms to enforce structure at the boundary. The practical step is to enforce schema validation as a hard gate: if data doesn't conform, it should not enter the pipeline. Alert on violations rather than silently dropping or coercing records without logging.
Best for: Teams consuming data from external APIs, third-party vendors, or multiple internal teams where you do not own the upstream system.
Watch out: Overly rigid schemas can cause unnecessary failures when benign additive changes occur upstream. Design validation to be strict on breaking changes (field removal, type changes) but tolerant of additive ones (new optional fields), and version your schemas explicitly.
Data Quality Profiling and Anomaly Detection
Data quality profiling is the systematic measurement of properties such as completeness, uniqueness, consistency, and distribution across a dataset or data stream. Poor data quality is, according to industry research cited by IEEE, one of the leading causes of AI model failures in production — making this not an optional hygiene step but a core reliability concern.
Establish baseline statistics on your training and serving data early: mean, median, standard deviation, null rates, and cardinality for key features. Then instrument your pipeline to continuously compare incoming data against those baselines. Sudden shifts in feature distributions — often called "data drift" — are a signal that either the upstream source changed or real-world conditions shifted in ways the model has not seen. Catching this at the pipeline level, before it affects predictions, is far cheaper than debugging degraded model outputs after the fact.
Best for: Any AI application where the input data is generated by real-world processes — user behavior, sensor readings, transaction records — where distributions naturally shift over time.
Watch out: Anomaly detection systems generate false positives. Invest time in tuning thresholds based on observed variance in your actual data rather than applying generic defaults, or you will create alert fatigue that causes teams to ignore real signals.
Idempotent and Replayable Pipeline Stages
An idempotent pipeline stage is one that produces the same output when run multiple times on the same input — meaning retries and replays do not corrupt state or generate duplicate records. Replayability means the pipeline can process historical data from any point in time to rebuild state, recover from failures, or backfill new features.
In practice, this means designing each processing step to be stateless where possible, using content-addressed storage or deterministic IDs, and separating raw storage from processed outputs so source data is never mutated. Audit logs and append-only storage patterns (such as event sourcing) are foundational here. If a pipeline stage cannot be safely replayed, it becomes a liability: any failure in production requires manual intervention rather than automated recovery.
Best for: Pipelines that feed training jobs, feature stores, or any downstream system that requires historical consistency and audit trails.
Watch out: Idempotency is harder to achieve when pipeline stages have side effects (sending emails, charging payments, calling external APIs). Isolate side-effect-producing steps and gate them with deduplication checks.
Feature Store Integration and Training-Serving Skew Prevention
Training-serving skew is the condition where features computed during model training differ — even subtly — from features computed at inference time, leading to systematic prediction errors that are difficult to diagnose. This is one of the most insidious production failure modes in AI systems, and it originates entirely in the data pipeline.
A feature store — a centralized system that computes, stores, and serves features consistently for both training and online inference — is the structural solution. Whether you build or adopt an existing solution, the critical design requirement is a single feature computation definition used in both contexts, with point-in-time correct retrieval for training and low-latency retrieval for serving. If you are evaluating whether to build or adopt existing infrastructure, our analysis of build vs. buy decisions for AI infrastructure covers the trade-offs relevant to feature store choices specifically.
Best for: Teams running multiple models in production, or any application where inference latency requirements make pre-computed features necessary.
Watch out: Feature stores add operational overhead and a new system to maintain. If your application is simple and inference is batch-only, a simpler approach using versioned dataset snapshots may be sufficient. Do not over-engineer early.
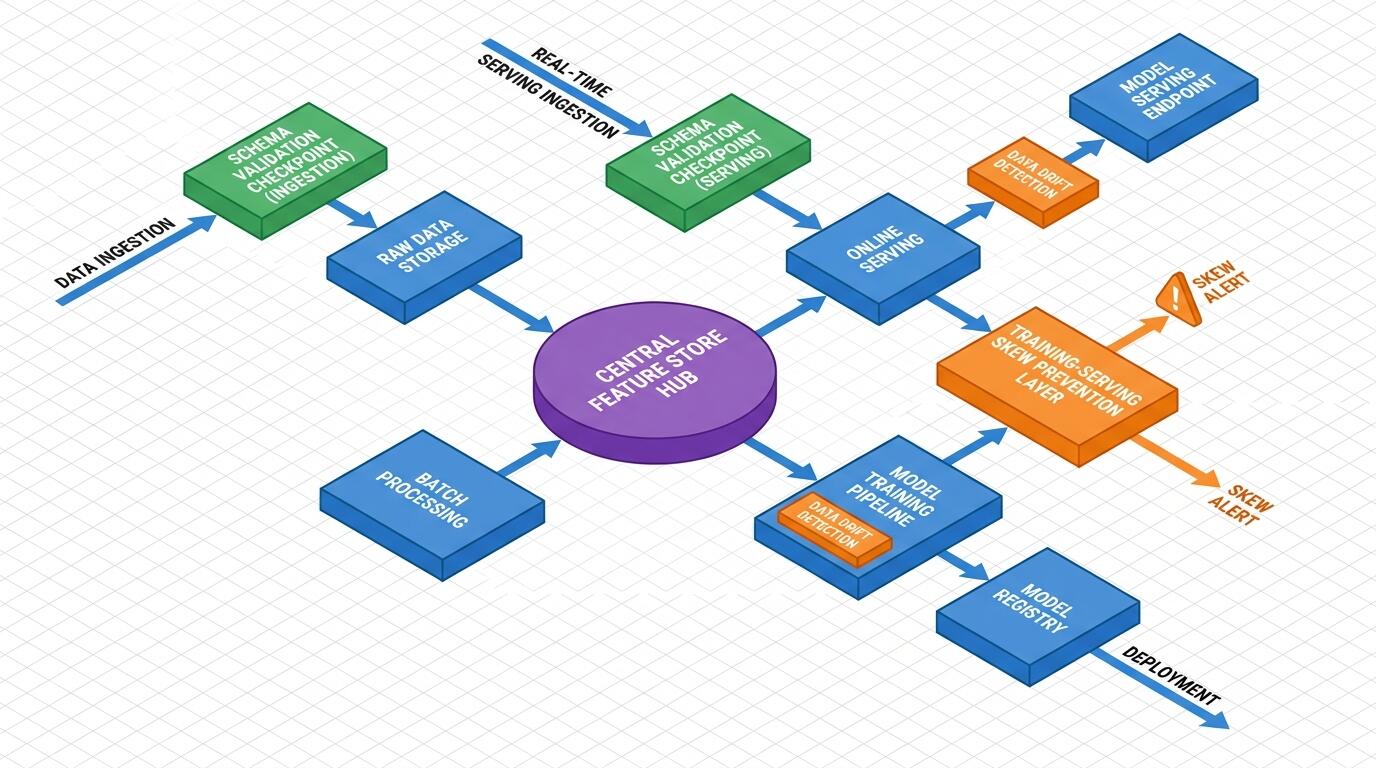 ALT: Diagram of AI data pipeline stages showing feature store integration, schema validation, and training-serving skew prevention for production AI apps
Lineage Tracking and Audit Traceability
Data lineage is the recorded history of where data came from, how it was transformed, and where it flows to — enabling debugging, compliance, and impact analysis. Without lineage, answering the question "which training run used which version of which dataset?" becomes forensic investigation rather than a routine lookup.
Lineage tracking operates at two levels: dataset-level lineage (which source systems contributed to a dataset) and column-level lineage (which transformations affected a specific feature). Both matter for AI systems. Dataset lineage supports reproducibility — a requirement called out in emerging AI governance frameworks including guidance from the National Institute of Standards and Technology (NIST) on trustworthy AI. Column-level lineage supports debugging, particularly when a feature is found to have been incorrectly computed or leaked future information.
Best for: Regulated industries (financial services, healthcare) and any team that needs to reproduce a specific model training run or explain a prediction to an external stakeholder.
Watch out: Full column-level lineage is expensive to implement and maintain. Prioritize lineage on features that are high-risk (used in consequential decisions) or frequently changed, rather than attempting comprehensive tracking from day one.
Scalable Ingestion Architecture with Backpressure Handling
A scalable ingestion architecture is one that can absorb variable-rate data inputs without data loss, excessive latency, or downstream system overload — specifically by implementing backpressure mechanisms that signal upstream producers to slow down when the system is at capacity. Without backpressure, a traffic spike can overwhelm processing stages, causing silent data loss or cascading failures.
Message queues such as Apache Kafka provide durable buffering and enable consumers to process at their own pace while producers continue writing. The key design decision is whether your pipeline needs stream processing (low-latency, event-by-event) or micro-batch processing (slightly higher latency, higher throughput efficiency). Most production AI pipelines benefit from a tiered approach: a streaming layer for real-time features and a batch layer for compute-intensive transformations. For a deeper treatment of how this architecture scales past the prototype stage, building machine learning pipelines that scale beyond prototype covers the specific architectural patterns in detail.
Best for: Applications with variable or unpredictable input rates — user-generated events, API-driven ingestion, IoT telemetry.
Watch out: Message queues introduce operational complexity: consumer lag monitoring, offset management, and topic partition tuning all require ongoing attention. Size your partitions and consumer groups based on measured throughput, not assumptions.
Secrets Management and Data Access Controls
Secrets management in AI data pipelines refers to the secure handling of credentials, API keys, database connection strings, and encryption keys required to access data sources and sinks — ensuring these are never hardcoded, logged, or exposed in pipeline configurations. Data access controls define which pipeline components and personnel can read, write, or transform specific datasets.
Per guidance from the Open Web Application Security Project (OWASP), hardcoded credentials in application code and pipeline configurations are a consistently top-ranked security risk. In AI systems, the exposure is compounded: training data often contains sensitive information, and a compromised pipeline can exfiltrate large volumes silently. Use a dedicated secrets management service (HashiCorp Vault, AWS Secrets Manager, or equivalent), enforce least-privilege access at the dataset level, and audit access logs regularly.
Best for: Any production pipeline — this is non-negotiable regardless of company size or data sensitivity level.
Watch out: Access control systems can become bottlenecks for development velocity if not designed with self-service in mind. Build an access request and provisioning workflow so controls do not become a manual overhead that teams work around.
Pipeline Observability: Metrics, Logging, and Alerting
Pipeline observability is the capability to understand the internal state of a data pipeline from its external outputs — specifically through structured metrics (throughput, latency, error rates), detailed logs, and actionable alerts configured on meaningful thresholds. A pipeline without observability is, in practice, unmanageable in production.
Observability for AI data pipelines extends beyond standard application monitoring. You need visibility into data-layer metrics — record counts, null rates, processing lag, schema violation counts — not just infrastructure metrics like CPU and memory. According to the DORA (DevOps Research and Assessment) research program, teams with high observability maturity resolve incidents significantly faster than those without. Instrument each stage of the pipeline, centralize logs, and define alert thresholds on leading indicators (rising null rates, growing consumer lag) rather than only lagging ones (pipeline failure). If you are at the stage of defining an observability strategy across your broader AI system, the AI architecture engagement process covers how observability is embedded from the design phase rather than retrofitted.
Best for: All production pipelines, but especially those where pipeline failure has direct user-facing consequences such as degraded model outputs or missing features.
Watch out: Observability tooling can generate enormous volumes of data. Define a tiered retention policy: high-resolution metrics for the recent window, aggregated metrics for longer-term trend analysis, and archive raw logs only as long as compliance requires.
Quick Comparison at a Glance
The eight checklist items address distinct dimensions of pipeline reliability. The table below maps each item to the failure mode it prevents and the team context where it delivers the most value.
| Checklist Item | Best For | Key Strength | Limitation |
|---|---|---|---|
| Data Source Contracts and Schema Validation | Teams with external or multi-team data sources | Catches breaking upstream changes at ingestion time | Requires upstream coordination to establish and maintain contracts |
| Data Quality Profiling and Anomaly Detection | Real-world, distribution-shifting data sources | Surfaces data drift before it degrades model performance | Threshold tuning is required to avoid alert fatigue |
| Idempotent and Replayable Pipeline Stages | Training pipelines, feature backfill, failure recovery | Enables safe retries and historical reprocessing | Harder to achieve when pipeline stages have external side effects |
| Feature Store Integration | Multi-model systems, low-latency inference | Eliminates training-serving skew structurally | Adds operational complexity; may be over-engineering for simple batch systems |
| Lineage Tracking and Audit Traceability | Regulated industries, reproducibility-critical teams | Supports compliance, debugging, and reproducibility | Full column-level lineage is expensive; prioritize high-risk features first |
| Scalable Ingestion with Backpressure | Variable-rate or high-throughput ingestion | Prevents data loss and cascading failures under load spikes | Message queues add operational overhead: lag, partitioning, consumer management |
| Secrets Management and Access Controls | All production pipelines (non-negotiable) | Prevents credential exposure and unauthorized data access | Can slow development velocity without a well-designed self-service workflow |
| Pipeline Observability | All production pipelines, especially user-facing | Enables fast incident detection and resolution | Risk of instrumentation overload without disciplined retention policies |
How to Choose the Right Starting Point
Not every team needs to address all eight dimensions simultaneously. The practical approach is to sequence implementation based on the failure modes most likely to affect your specific system.
If your pipeline consumes data from external sources you do not control, prioritize schema validation and data source contracts first — schema drift from an upstream change is a common cause of silent failures that take days to diagnose. If your application makes consequential decisions (credit, healthcare, personalization at scale), lineage tracking and access controls should be addressed before you scale.
If your primary risk is model performance degradation over time, data quality profiling and anomaly detection belong at the top of your roadmap. If you are moving from prototype to production and scaling throughput, idempotency and scalable ingestion architecture should come first — these are the structural choices that become extremely costly to retrofit later.
A common misconception is that production readiness is a final milestone — something you achieve once before launch. In practice, pipeline readiness is an ongoing operational posture. Systems that were production-ready at launch can drift out of readiness as traffic patterns change, data sources evolve, and team knowledge of the system erodes. The checklist is most valuable when used as a recurring review, not a one-time gate.
For teams that are still in the evaluation phase — deciding which tools and vendors to commit to — the criteria in this checklist also serve as a framework for vendor assessment. Each item maps to capabilities you should verify before signing any infrastructure contract.
Frequently Asked Questions FAQ
Q1: How do you prevent training-serving skew in a production AI pipeline?
Training-serving skew is prevented by ensuring that the feature computation logic used during model training and the logic used at inference time are derived from a single, shared definition — ideally enforced through a feature store. The structural cause of skew is maintaining two separate codepaths for the same feature. Using a unified feature store with point-in-time correct retrieval for training and low-latency retrieval for serving eliminates this divergence at the architectural level, rather than relying on manual discipline to keep two implementations synchronized.
Q2: Is schema validation necessary if the team owns both the data source and the consumer?
Schema validation is still valuable even when a single team owns both sides of a data interface, because it enforces explicit contracts that protect against accidental breaking changes during development. Internal pipelines are frequently broken by well-intentioned refactoring that changes a field name or type without considering downstream consumers. Schema validation provides a mechanical check that catches these changes before they reach production, regardless of team ownership. The cost of implementing validation is low; the cost of debugging a silent schema break in production is high.
Q3: How long does it typically take to instrument a pipeline with full observability?
Instrumenting a pipeline with meaningful observability — covering throughput, error rates, data-quality metrics, and alerting — typically takes between a few days for a simple single-stage pipeline and several weeks for a multi-stage distributed system, depending on the existing tooling in place and the complexity of the data flow. The most time-intensive step is usually defining alert thresholds based on real observed behavior rather than arbitrary defaults. Starting with a small set of high-signal metrics and expanding incrementally is more effective than attempting comprehensive instrumentation in a single sprint.
Summary
A production-ready AI data pipeline is defined not by the sophistication of its processing logic but by the reliability of its operational foundations: validated inputs, observable internals, secure access, and the structural guarantees that make the system recoverable when things go wrong.
Key Takeaways:
- Schema validation and data source contracts are the first line of defense against silent upstream failures that corrupt model inputs.
- Training-serving skew is a structural problem that requires a structural solution — feature stores or equivalent shared computation definitions.
- Idempotency and replayability are architectural decisions that must be made early; they are difficult and costly to retrofit.
- Observability at the data layer — not just the infrastructure layer — is what enables fast diagnosis when model behavior changes unexpectedly.
- Production readiness is an ongoing operational posture, not a one-time pre-launch gate.
The highest-leverage next step is to run this checklist against your current pipeline architecture and identify which items are not yet addressed. Focus first on the gaps that correspond to the failure modes most likely in your specific system, then sequence the remaining items into your engineering roadmap.
Explore real shipped projects, in-depth technical writing, and the full professional background behind this work at the Darius website. Whether you are building a new AI-powered product from the ground up or scaling a system that is already in production, connect to discuss what end-to-end technical leadership looks like in practice.
Sources & Further Reading
- National Institute of Standards and Technology (NIST). "AI Risk Management Framework."
- IEEE. "Standards and Research on AI System Reliability and Data Quality."
- Open Web Application Security Project (OWASP). "Security Risks in Application and Pipeline Configurations."
- DORA (DevOps Research and Assessment). "Research on Software Delivery Performance and Observability Maturity."
Note: Standards and guidance documents may be updated; please check the latest official publications or consult qualified professional advisors before making architectural decisions based on regulatory or compliance requirements.