
AI System Architecture Checklist for CTOs Heading Into Q4 2026
Summary
A pre-Q4 2026 AI architecture audit checklist for CTOs and engineering leads, covering 8 critical areas: inference cost/latency, RAG pipeline quality, model versioning, AI observability, data pipeline integrity, endpoint security, governance, and capacity planning. Key argument: architectural debt surfaces under peak load — audit now to ship features instead of firefighting in Q4.
Details
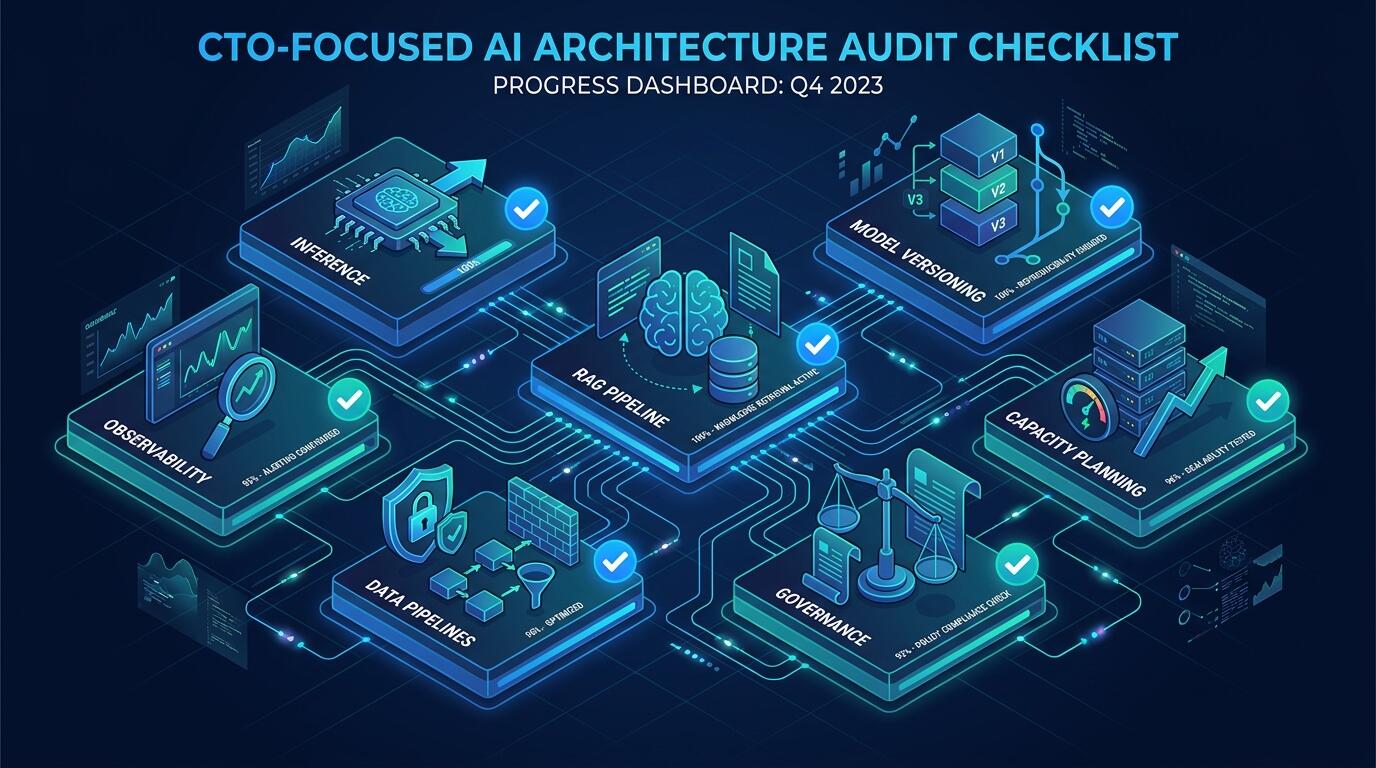 ALT: AI system architecture checklist for CTOs planning scalable AI infrastructure heading into Q4 2026
What Every CTO Should Audit Before Q4 2026 Hits
A pattern that shows up repeatedly in conversations with technical leaders: the engineering team has been executing well all year, models are deployed, pipelines are running — and then Q4 arrives with its surge in traffic, board-level scrutiny, and product commitments that suddenly feel much closer than they did in January. That's when architectural shortcuts taken during rapid build phases start showing their true cost.
This checklist exists to surface those risks before they become incidents. It's built for CTOs, engineering directors, and senior technical leads who are responsible for AI-powered systems at meaningful scale — not for teams still prototyping, but for those with something real running in production or close to it.
The items below were selected based on recurring patterns observed in real AI system design and delivery work: the failure modes that appear most consistently, the decisions that tend to get deferred the longest, and the gaps most likely to cause problems at exactly the wrong moment. Use this list as a structured audit, not a sequential build guide. Some items you'll be able to check off immediately; others will open conversations that are worth having now rather than under pressure.
The Checklist: Eight Architecture Areas to Audit Before Q4 2026
Inference Cost and Latency Are Modeled at Real Production Load
AI inference costs are non-linear. A system that runs comfortably at median load can become prohibitively expensive or unacceptably slow when traffic spikes — and Q4 is historically when those spikes arrive. Many teams have a rough sense of their cost per request at average load but have never stress-tested the architecture at two to five times that volume.
A credible audit here means verifying that you have actual load test results, not estimates, for the traffic levels your product could realistically see. It also means understanding where your latency budget is being spent: is the bottleneck the model, the retrieval layer, the database, or network overhead? Each has a different remediation path, and conflating them leads to expensive, misdiagnosed interventions.
Best for: Teams running LLM-backed features in production where user experience is directly tied to response time, or where API costs represent a meaningful portion of operating expenses.
Watch out: Benchmarking in isolation (a single model call, no retrieval, no downstream services) gives latency numbers that bear little resemblance to what users experience. Always test the full request path.
Retrieval-Augmented Generation (RAG) Pipeline Quality Is Measured, Not Assumed
Retrieval-Augmented Generation (RAG) is an AI architecture pattern in which a language model generates responses conditioned on documents retrieved at query time from an external knowledge base. RAG has become the dominant approach for grounding LLM outputs in proprietary or up-to-date information — but the quality of a RAG pipeline degrades silently. Embedding drift, stale indexes, and retrieval precision problems don't throw exceptions; they produce subtly wrong answers that erode user trust over time.
The audit question here is specific: do you have an evaluation framework that measures retrieval recall and answer faithfulness on a representative test set, and is it running on a schedule? In work with teams building RAG-backed products, one of the most consistent findings is that evaluation is set up once during development and then quietly stops being monitored. By the time a quality regression is noticed, the root cause is buried in months of index updates.
Best for: Any product where factual accuracy or compliance matters — support automation, internal knowledge tools, regulated industry applications.
Watch out: Standard RAG evaluation metrics (like faithfulness and context recall) measure what the pipeline does, not what users actually need. Pair automated metrics with periodic human spot-checks.
Model Versioning and Rollback Are Operationally Tested
Model versioning is the practice of maintaining distinct, addressable versions of a trained or fine-tuned AI model so that any prior version can be restored and served without redeployment of the broader system. Most teams have version control for their model artifacts in theory. Fewer have actually executed a rollback under time pressure and confirmed that it worked correctly end-to-end, including downstream schema compatibility.
Per the AI Roadmap for CTOs published by Amazing CTO, one of the clearest operational risks heading into high-stakes delivery periods is the assumption that rollback is possible without having verified it. A model update that degrades output quality, breaks a downstream parser, or changes response format in unexpected ways needs to be reversible in minutes, not hours.
Best for: Teams that have shipped multiple model iterations and are now running fine-tuned or customized models where provider-managed versioning isn't available.
Watch out: Rollback of the model artifact is not sufficient if the prompt templates, retrieval indexes, or application logic have also changed. Version these dependencies together or you'll roll back the model into an incompatible runtime environment.
Observability Covers Model Behavior, Not Just Infrastructure
Standard application observability — CPU, memory, error rates, request latency — does not tell you whether your AI system is behaving correctly. A model can be responding at acceptable latency, with zero 5xx errors, while producing outputs that are drifting from acceptable quality. This is a category error that causes CTOs to believe their system is healthy when it isn't.
Effective AI observability includes logging a representative sample of inputs and outputs for human or automated review, tracking distributions of model outputs over time (so drift is detectable), and alerting on proxy quality signals — things like user feedback rates, downstream action failure rates, or structured output parse failures. According to the CTO Checklist for AI-Ready IT Operations published by ITSM Tools, the organizations making the most progress on AI reliability in 2026 are those that treat model behavior as a first-class observable.
Best for: Any team where AI outputs drive user-facing features or downstream automated decisions.
Watch out: Logging everything at high volume generates cost and creates privacy surface area. Sample strategically and ensure your logging infrastructure complies with applicable data handling requirements.
Data Pipeline Integrity Is Validated Upstream of Model Training and Inference
AI systems inherit the errors, biases, and schema changes of the data pipelines that feed them. A pattern that appears consistently in production AI work: a schema change in an upstream database silently corrupts a feature pipeline, the model continues to run, and the degradation only surfaces when someone notices unexpected outputs weeks later.
The audit here covers two areas. For training pipelines: do you have data validation checks that run before any model retraining job, and do failures halt the pipeline rather than propagate silently? For inference pipelines: are the features computed at serving time consistent with the features used during training — the classic training-serving skew problem — and is that consistency verified on a schedule?
Best for: Teams with real-time or near-real-time inference that depends on feature pipelines, or any team that retrains models on a schedule using production data.
Watch out: Data validation frameworks can generate false confidence if the validation rules themselves are stale. Treat your data contracts as living documents that need to be reviewed when upstream systems change.
Security and Access Control Around AI Endpoints Are Explicitly Scoped
AI inference endpoints are API surfaces, and they carry risks that differ from conventional APIs. Prompt injection — where adversarial input causes a model to ignore its system instructions — is a documented attack class that remains poorly understood at the organizational level. Model outputs can also leak information present in the context window, including retrieval results that contain sensitive data.
The checklist question here is whether your security posture for AI endpoints has been explicitly reviewed with AI-specific threat models in mind, not just mapped onto generic API security practices. This includes input validation, output filtering for sensitive content, rate limiting calibrated to model costs rather than just server load, and access scoping that limits which users or services can trigger expensive inference paths.
Best for: Teams exposing AI features to external users, or where the model has access to sensitive internal knowledge bases or user data.
Watch out: Over-relying on the model provider's safety guardrails as your primary defense. Provider-level filters are a useful layer but are not a substitute for application-level input/output handling.
Organizational AI Governance and Compliance Posture Is Documented
AI governance refers to the documented policies, accountability structures, and audit mechanisms that an organization maintains to ensure its AI systems behave within defined ethical, legal, and operational boundaries. As AI regulation matures globally — with frameworks emerging from regulators in the EU, US, and other jurisdictions — the question is no longer whether governance is needed but whether your organization's posture is documented well enough to demonstrate compliance under scrutiny.
For Q4 2026, the practical question is: if a regulator, a customer, or your own board asked how a specific AI decision was made and what controls exist around it, could you answer that within a reasonable timeframe? The documentation gap here is often not in the policies themselves but in the traceability — the ability to connect a specific output to the model version, the data it was trained on, and the policy framework governing its use.
Best for: Companies in regulated industries, those with EU market exposure (given the AI Act's progressive enforcement timeline), and any team that has made public commitments around responsible AI use.
Watch out: Treating governance as a one-time documentation exercise. The value is in maintaining living records that reflect the system as it actually operates, not as it was designed to operate.
Capacity Planning Accounts for AI-Specific Resource Patterns
Standard cloud capacity planning handles compute, storage, and network. AI systems introduce resource patterns that don't fit neatly into those categories: GPU memory constraints that make horizontal scaling non-linear, context window limits that create hard ceilings on request complexity, and token throughput limits from model providers that interact unpredictably with traffic bursts.
As noted in the analysis by Prove AI on what CTOs are navigating heading into the back half of this decade, the teams that manage AI infrastructure costs effectively are those that treat token economics and GPU memory as primary planning variables, not afterthoughts. The audit here means verifying that your capacity models include these AI-specific constraints and that you have documented escalation paths when you approach provider-side limits.
Best for: Any team with material AI infrastructure costs, or those approaching rate limits with current providers.
Watch out: Vendor rate limit increases often require advance notice and account-level negotiation. Don't discover your throughput ceiling for the first time during a high-traffic event.
Quick Comparison at a Glance
| Checklist Item | Best For | Key Strength | Limitation |
|---|---|---|---|
| Inference cost and latency modeling | LLM features with UX or cost sensitivity | Surfaces scalability issues before they become incidents | Requires realistic load test infrastructure to produce useful results |
| RAG pipeline quality measurement | Knowledge-grounded products requiring factual accuracy | Catches silent retrieval and quality regressions | Metrics must be paired with human review to catch nuanced failures |
| Model versioning and rollback | Teams with multiple model iterations in production | Ensures recovery path exists for bad model updates | Must version prompts and retrieval indexes alongside model artifacts |
| AI-specific observability | Any AI feature driving user-facing or automated decisions | Makes model behavior degradation detectable | High-volume logging carries cost and data privacy implications |
| Data pipeline integrity validation | Teams with feature pipelines or scheduled model retraining | Prevents silent data corruption from propagating to model outputs | Validation rules themselves can become stale if not maintained |
| AI endpoint security and access control | External-facing AI features or sensitive knowledge base access | Addresses AI-specific attack surfaces like prompt injection | Provider guardrails are a layer, not a substitute for application-level controls |
| AI governance and compliance documentation | Regulated industries, EU market exposure, public AI commitments | Enables traceability and accountability under scrutiny | Requires ongoing maintenance to reflect the system as it operates |
| AI-specific capacity planning | Teams with material AI infrastructure costs or approaching rate limits | Manages GPU memory and token economics as primary variables | Rate limit escalation with providers requires advance negotiation |
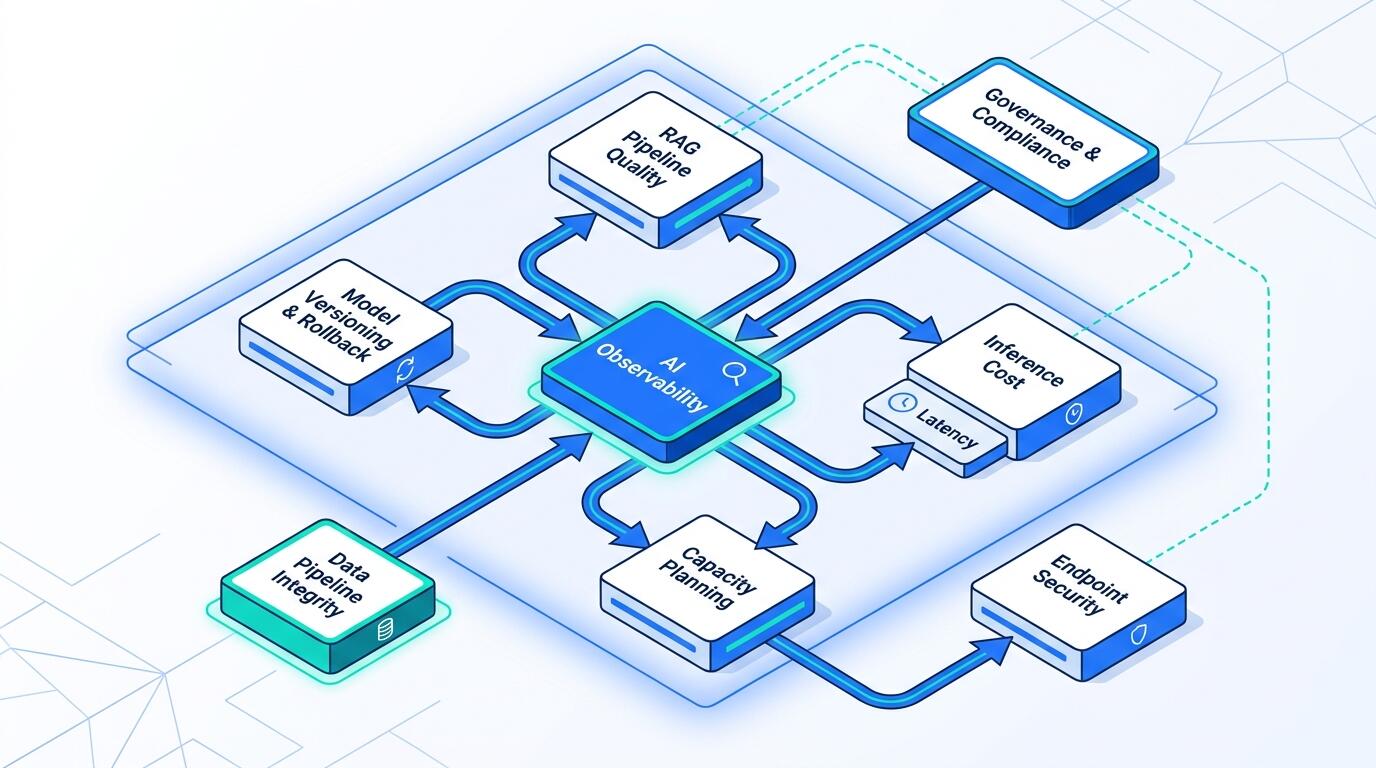 ALT: Diagram illustrating AI system architecture audit areas including inference, observability, data pipelines, security, and governance for CTOs planning Q4 2026 readiness
How to Prioritize This Checklist for Your Specific Situation
The eight items above don't all carry equal urgency for every team, and the right order depends on where your system currently sits.
If you're running a customer-facing AI feature with variable traffic, start with inference cost and latency modeling and capacity planning. These are the items most likely to produce a visible incident under load, and they have the longest remediation timelines if infrastructure changes are required.
If your core product relies on a RAG architecture or other retrieval-grounded approach, RAG pipeline quality measurement and data pipeline integrity should be your second priority. Silent quality degradation is the failure mode that's hardest to detect and easiest to underestimate, because users often stop complaining about wrong answers long before you know they're getting them.
For teams in regulated industries or with significant EU market exposure, governance and compliance documentation deserves immediate attention regardless of your technical maturity level. The enforcement timeline for frameworks like the EU AI Act is not hypothetical, and the documentation work takes longer than most teams expect.
A common misconception worth addressing directly: observability is often treated as an infrastructure concern that the platform team owns. In practice, AI-specific observability — logging model inputs and outputs, tracking output distributions, surfacing quality proxy signals — requires explicit investment from the team building the AI features, not just the team running the infrastructure. If that ownership isn't clearly assigned, it typically doesn't happen.
For teams that are strong on the technical items but have gaps in security and access control, prioritize the AI endpoint security audit before Q4. This is the area where the threat model has evolved most significantly in the past year, and where mapping onto legacy API security practices leaves the most meaningful gaps unaddressed.
Frequently Asked Questions FAQ
Q1: How do I know if my current AI observability setup is actually sufficient for production?
Sufficient AI observability for production means you can detect model output quality degradation without a user report — your monitoring catches it first. If your current setup only tracks infrastructure metrics (latency, error rate, uptime) and has no mechanism for sampling and reviewing model outputs or tracking output distribution shifts over time, it is not sufficient. A practical starting point is logging a small, representative sample of production inputs and outputs and reviewing them on a structured schedule.
Q2: Are provider-managed model APIs sufficient for a production-grade AI architecture, or do teams need to self-host models?
Provider-managed APIs are sufficient for the majority of production use cases and are often the right choice, but they introduce dependencies that need to be explicitly managed: rate limits, model deprecation timelines, latency variability, and data residency constraints. A production-grade architecture accounts for these dependencies — through versioning, throughput planning, and fallback strategies — regardless of whether the model is hosted by a provider or self-deployed. Self-hosting adds operational complexity that is only warranted when specific constraints (cost at scale, data sovereignty, customization requirements) justify it.
Q3: How much time should a CTO budget to complete a meaningful AI architecture audit?
A lightweight audit — reviewing existing documentation, running targeted conversations with tech leads, and identifying the highest-priority gaps — can be completed in one to two weeks of focused work. A thorough audit that includes actual load testing, observability gap remediation, and governance documentation review typically takes four to eight weeks, depending on system complexity and team capacity. The ROI calculation is straightforward: the cost of the audit is almost always lower than the cost of a single high-severity production incident during a peak period.
The Bottom Line
Heading into Q4 2026, the AI systems that hold up under pressure won't be the ones with the most sophisticated models — they'll be the ones whose architecture was audited, stress-tested, and hardened before the pressure arrived.
Key Takeaways:
- Inference cost and latency must be validated at realistic production load, not median load — the gap between the two is where Q4 incidents originate.
- RAG pipeline quality degrades silently; automated evaluation frameworks that run on a schedule are the only reliable defense.
- Model versioning is not complete until rollback has been operationally tested end-to-end, including prompt and retrieval index compatibility.
- AI-specific observability requires explicit ownership and investment from the product engineering team, not just the infrastructure team.
- Governance documentation is a technical deliverable, not a compliance checkbox — it needs to reflect the system as it actually operates.
Run this checklist now, assign clear owners to each gap, and set a resolution timeline before Q4 planning is locked. The teams that do this work in advance are the ones that spend Q4 shipping instead of firefighting.
If the architectural gaps surfaced by this checklist look familiar — or if you're looking for a technical partner who can move from audit to implementation without losing momentum — explore Darius's work, shipped projects, and technical approach at darius.wiki. From AI architecture design through to production deployment, it's the kind of end-to-end engineering partnership that closes the gap between a good plan and a working system.
References & Further Reading
- ITSM Tools. "The CTO Checklist for AI-Ready IT Operations in 2026".
https://itsm.tools/the-cto-checklist-for-ai-ready-it-operations-in-2026/
- Prove AI. "2026 and Beyond: A CTO's View on What's to Come".
https://proveai.com/blog/2026-and-beyond-a-ctos-view-on-whats-to-come
- Amazing CTO. "The AI Roadmap for CTOs [2026]".
https://www.amazingcto.com/ai-roadmap-for-ctos/
Note: Standards and regulatory frameworks may be updated; please check the latest official documents or consult professional advisors for current requirements.