
GPU Utilization Tactics Worth Trying Before You Scale Further
Summary
A technical deep-dive for AI engineers, startup CTOs, and engineering leaders on maximizing GPU utilization before scaling hardware. Covers 7 actionable tactics—profiling, gradient accumulation, mixed precision (AMP/BF16), data pipeline optimization, memory management, quantization, and multi-GPU tuning—with a troubleshooting table, pro tips, and FAQ. Core argument: measure and optimize first; scale only from an efficient baseline.
Details
 ALT: GPU utilization tactics for AI engineers optimizing compute before scaling infrastructure further
Squeeze More From What You Have: GPU Utilization Tactics That Matter Before You Scale
GPU underutilization is one of the most expensive and least visible problems in AI infrastructure. Teams often respond to slow training runs or high inference latency by provisioning more hardware — only to find that the bottleneck was never the hardware count in the first place. This guide is for engineering leaders, startup CTOs, and senior engineers who want to get the most out of existing GPU capacity before committing to a larger footprint. If your workloads are running, but not running well, what follows are the tactics worth auditing first.
Before You Start: Prerequisites and Preparation for GPU Optimization
Effective GPU utilization work requires more than good intentions — it requires instrumentation. Before you can optimize, you need visibility. The single most common mistake teams make at this stage is trying to improve performance without first measuring it precisely.
You should have a working familiarity with your current stack: which framework you are using (PyTorch, JAX, TensorFlow, or otherwise), whether you are training, fine-tuning, or serving inference, and what your current hardware topology looks like (single GPU, multi-GPU single node, or multi-node distributed). You do not need to be an expert in all of these areas, but you do need enough context to interpret profiling data meaningfully.
Profiling tools are non-negotiable starting points. NVIDIA's NSight Systems and NSight Compute are the most capable options for deep GPU-level analysis. PyTorch's built-in profiler provides a lower-friction starting point for most ML engineers. Weights and Biases, MLflow, or similar experiment trackers help you baseline performance across runs, which is essential for knowing whether a change actually improved things.
You should also know your target metrics before you begin. GPU memory utilization, GPU compute utilization (often called SM utilization), memory bandwidth saturation, and host-to-device transfer time are the primary signals. Aiming to improve "GPU performance" in the abstract is too vague to be actionable.
Checklist before starting:
- Profiling tooling is installed and producing readable output on your target hardware
- You have a representative benchmark workload — not a toy example, not your full production job
- Baseline metrics are recorded: compute utilization, memory utilization, throughput, and latency
- You understand your current batch size strategy and why it was chosen
- You know which parts of the pipeline are CPU-bound versus GPU-bound
- You have a staging or development environment that closely mirrors production hardware
The time investment for a thorough optimization pass varies considerably by workload complexity. Plan for it to be iterative — a single afternoon rarely moves the needle meaningfully. Sustained, methodical measurement and adjustment is what produces durable gains.
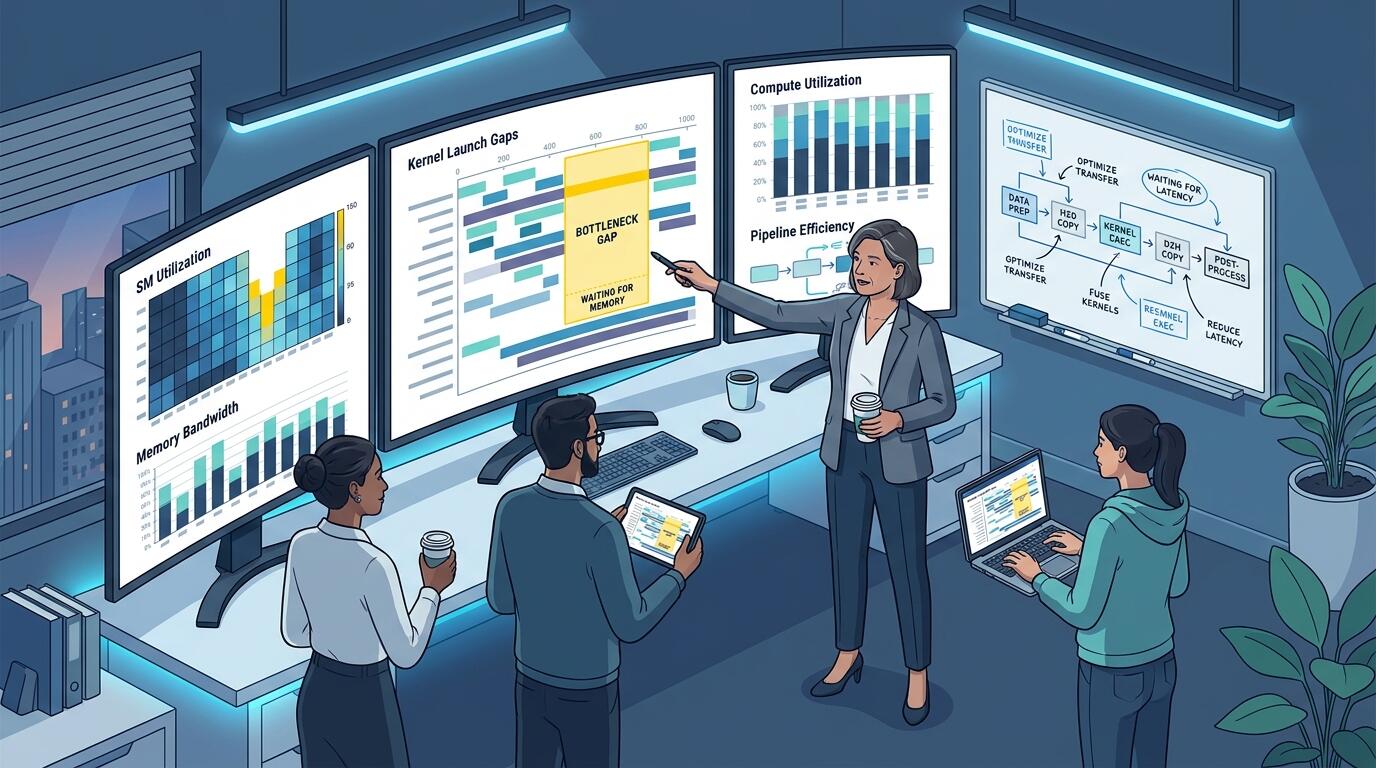 ALT: Engineering team reviewing GPU profiling output to identify utilization bottlenecks in AI training pipeline before scaling cluster
Step-by-Step GPU Utilization Tactics Worth Applying Now
Step 1: Profile First — Identify Where GPU Time Is Actually Going
The most valuable thing you can do before making any change is profile your workload end to end. GPU utilization figures from a system monitor are surface-level — they tell you the GPU is busy, but not what it is busy doing. Kernel-level profiling reveals idle gaps, memory transfer stalls, and CPU synchronization points that aggregate dashboards obscure.
Run a representative training step or inference request through NVIDIA NSight Systems or PyTorch's torch.profiler module. Export the trace and look for three patterns: long gaps between kernels (indicating CPU-to-GPU synchronization bottlenecks), repeated small kernel launches (indicating excessive Python overhead or poor operator fusion), and high memory transfer time relative to compute time (indicating data pipeline issues).
Tip: Focus on the critical path through the trace, not the longest individual kernel. A fast kernel that runs sequentially after many CPU-side delays is less of a problem than it appears.
Step 2: Increase Effective Batch Size Using Gradient Accumulation
Larger batches improve GPU compute efficiency by amortizing kernel launch overhead across more work per step. However, raw batch size is constrained by GPU memory capacity. Gradient accumulation is the practical solution: you accumulate gradients across multiple forward-backward passes before performing a parameter update, achieving the statistical effect of a larger batch without exceeding memory limits.
Implement gradient accumulation by running N micro-steps with optimizer.zero_grad() deferred until after all N steps complete. The effective batch size becomes N multiplied by the per-step batch size. Per IEEE documentation on distributed machine learning practices, gradient accumulation is a standard technique for bridging the gap between memory constraints and training stability requirements.
Tip: Be aware that gradient accumulation changes the frequency of optimizer steps, which affects learning rate schedules. Adjust your scheduler accordingly, treating one accumulation cycle as one optimizer step.
Step 3: Enable Mixed Precision Training With AMP
Mixed precision training uses 16-bit floating point (FP16 or BF16) for most operations while retaining 32-bit precision where it matters for numerical stability. According to NVIDIA's documentation on Tensor Core architectures, FP16 and BF16 matrix multiplications on modern Ampere and Hopper generation GPUs execute at significantly higher throughput than their FP32 equivalents, because Tensor Cores are specifically designed for reduced-precision arithmetic.
PyTorch's torch.cuda.amp module makes this straightforward to implement via automatic mixed precision (AMP). Wrap your forward pass in torch.autocast and use GradScaler to prevent gradient underflow. BF16 is generally preferred over FP16 for training because it has the same dynamic range as FP32 and eliminates the need for loss scaling in most cases — a meaningful reduction in implementation complexity.
Tip: Not all operations benefit from reduced precision. Layer normalization and loss computation often need FP32. AMP handles this automatically, but verify by checking for NaN gradients in your early training steps.
Step 4: Eliminate Data Pipeline Bottlenecks
A GPU sitting at low utilization while waiting for data is a data pipeline problem, not a GPU problem. This pattern is pervasive in teams that iterate quickly on modeling architecture without revisiting their data loading infrastructure. In practice, it is one of the patterns most frequently encountered when reviewing underperforming training setups.
Diagnose this by monitoring GPU utilization over time at fine granularity. If you see periodic dips to near-zero that correlate with data loading operations, the pipeline is the constraint. Solutions include increasing DataLoader worker count, using pinned memory (pin_memory=True in PyTorch DataLoader), prefetching batches asynchronously, and — for large datasets — switching to streaming formats such as WebDataset or NVIDIA DALI, which move preprocessing onto the GPU.
For teams building production ML pipelines, ensuring data infrastructure scales alongside model complexity is foundational. The guide on how to build machine learning pipelines that scale past prototype stage covers this in detail, including the transition from research-grade data loading to production-grade throughput.
Tip: Benchmark your data pipeline in isolation by iterating through your DataLoader without running any model forward pass. The throughput ceiling this reveals is the maximum training speed your pipeline can support.
Step 5: Tune Memory Layout and Reduce Unnecessary Allocations
GPU memory management has a direct impact on compute throughput because frequent allocation and deallocation trigger memory fragmentation and garbage collection overhead. Reuse tensor allocations where possible. Avoid creating intermediate tensors inside tight loops. Use in-place operations when appropriate, with awareness of autograd constraints.
For inference specifically, enabling torch.inference_mode() (or torch.no_grad() for older versions) eliminates the overhead of tracking the computational graph entirely. This is a zero-cost correctness win that is frequently overlooked. Similarly, for models that will be deployed at scale, torch.compile() in PyTorch 2.x can fuse operators and reduce kernel launch overhead automatically — a meaningful throughput improvement for many architectures with minimal code change.
Memory layout also matters at the tensor level. Contiguous tensors in NCHW format (for CNNs) versus NHWC format can affect Tensor Core utilization depending on the hardware and operation. Profile before assuming a layout preference.
Tip: CUDA's caching allocator means that torch.cuda.empty_cache() rarely improves throughput — it releases memory back to the OS but does not defragment the cache in the way most engineers expect. Use it only when you genuinely need to free memory for a separate process.
Step 6: Apply Model Quantization for Inference Workloads
Quantization is the practice of representing model weights and activations in lower bit-width formats — INT8 or INT4 — to reduce memory footprint and increase inference throughput. For production inference workloads, this is one of the highest-leverage tactics available once a model is trained. A quantized model can serve significantly more requests per second on the same hardware compared to its FP32 baseline.
Post-training quantization (PTQ) applies quantization after training completes, requiring only a small calibration dataset. Quantization-aware training (QAT) incorporates quantization into the training process itself, generally producing better accuracy at aggressive bit widths but requiring more implementation effort. For most practical use cases, PTQ with INT8 is the starting point — NVIDIA's TensorRT and Hugging Face's bitsandbytes library both support this workflow.
Accuracy degradation under quantization varies by model architecture and task. Evaluate carefully on your validation set before deploying. Some layers — particularly attention mechanisms in transformer models — are more sensitive to quantization than others and may need to remain in higher precision.
Tip: Measure latency, throughput, and accuracy together. A quantized model that is faster but meaningfully less accurate has not improved your system — it has just shifted the failure mode.
Step 7: Optimize Multi-GPU Utilization Before Adding More GPUs
If you are already running on multiple GPUs, confirm that your parallelism strategy is matched to your workload characteristics before scaling the cluster further. Data parallelism (replicating the model, splitting the data) is effective when the model fits on a single GPU and the bottleneck is throughput. Tensor parallelism and pipeline parallelism are appropriate when the model itself exceeds single-GPU memory, but they introduce communication overhead that must be managed carefully.
Poorly configured distributed training frequently achieves lower GPU utilization across the fleet than a well-tuned single-GPU job. Per research documented by academic groups studying distributed deep learning (including work published through institutions such as Carnegie Mellon University and Stanford), all-reduce communication patterns and gradient synchronization overhead can dominate training time when not balanced against compute time per step.
Use NCCL's built-in profiling capabilities or PyTorch's distributed profiler to identify whether your multi-GPU setup is communication-bound. If gradient synchronization dominates, consider gradient compression, asynchronous communication with overlap enabled (find_unused_parameters=False in DDP, overlapping all-reduce with backward pass), or revisiting whether your model actually requires distribution at current scale. Before expanding your infrastructure footprint significantly, it is worth reviewing the build vs. buy framework for AI infrastructure decisions to ensure you are investing in the right direction.
Tip: Communication topology matters. On a single node with NVLink-connected GPUs, all-reduce is fast. Across nodes over InfiniBand or Ethernet, the cost increases substantially. Design your parallelism strategy with your actual interconnect in mind.
Common Mistakes and Troubleshooting in GPU Optimization
| Symptom | Likely Cause | How to Fix |
|---|---|---|
| GPU utilization reads high but throughput is low | Small, frequent kernel launches with high overhead between them | Batch operations, enable torch.compile() for operator fusion, or restructure model forward pass |
| GPU memory full but compute utilization low | Large activations stored unnecessarily for backprop | Use gradient checkpointing to trade compute for memory; review activation recomputation strategy |
| Training with AMP produces NaN losses early | Loss scaling issues with FP16, often in specific layers | Switch to BF16 if hardware supports it; inspect which layers produce NaN and keep them in FP32 |
| Multi-GPU training slower than single-GPU | Gradient synchronization dominates the step time | Profile communication overhead; reduce batch frequency of all-reduce; check NCCL topology configuration |
| Data pipeline saturates at scale | DataLoader workers bottlenecked by CPU preprocessing | Increase worker count, use pin_memory, switch to GPU-side preprocessing with NVIDIA DALI |
| Inference latency high despite good GPU utilization | Memory bandwidth saturation rather than compute saturation | Apply quantization to reduce model size; try KV cache optimization for transformer inference |
Pro Tips for Better GPU Utilization Results
Profile at the kernel level, not just the process level. System-level GPU utilization metrics are useful for a first pass, but they obscure the actual structure of your workload. A GPU that appears 90% utilized may be spending most of that time on memory copies rather than matrix multiplications. Kernel-level profiling with NSight Compute reveals the true arithmetic intensity of your workload — the ratio of compute operations to memory operations — which determines whether you are compute-bound or memory-bandwidth-bound and guides which optimizations to prioritize.
Treat batch size as a first-class hyperparameter for efficiency, not just for accuracy. Many teams select batch size based on memory limits and move on. In practice, the relationship between batch size, throughput, and hardware efficiency is non-trivial. There is often a range of batch sizes that maximizes GPU throughput well below the memory ceiling. Profiling throughput as a function of batch size across a range — not just the maximum that fits — frequently surfaces meaningful gains.
Operator fusion is underused in production models. When a model calls separate element-wise operations in sequence, each incurs a kernel launch and a round-trip to GPU memory. Fused kernels combine these into a single pass, dramatically reducing memory bandwidth consumption. torch.compile() automates this for many cases. For custom operations or specific performance-critical paths, writing fused CUDA kernels with Triton (an open-source GPU programming language designed for this purpose) gives explicit control. This is advanced work but highly effective for frequently-called operations.
Quantization and compilation are not mutually exclusive. A common misconception is that quantization is the only tool for inference optimization. In practice, combining torch.compile() with quantization, batched inference, and optimized KV caching for transformer-based models produces compounding gains. Treat these as a stack of optimizations to layer, not competing alternatives to choose between.
Validate on your real production traffic pattern, not a synthetic benchmark. Optimization gains measured on a static benchmark workload often do not transfer cleanly to production because real traffic has variable input lengths, dynamic batching requirements, and concurrency patterns that benchmarks do not capture. Build a representative load test that mirrors actual usage before declaring an optimization successful. This is especially relevant for inference serving, where tail latency under concurrency matters as much as average throughput.
Questions and Answers
Q1: How do I know if my GPU is compute-bound or memory-bandwidth-bound?
GPU compute-bound means the processor is saturated with arithmetic operations and cannot process them faster. Memory-bandwidth-bound means the GPU is waiting on data transfers rather than computing. The distinction determines which optimizations matter. Use NVIDIA NSight Compute to inspect the arithmetic intensity of your kernels — the ratio of floating point operations to bytes transferred. If your measured intensity falls below the hardware's roofline, you are memory-bound, and tactics like quantization and reduced precision will have more impact than increasing parallelism.
Q2: Is mixed precision training safe to use for all model types?
Mixed precision training is broadly safe but not universally so without care. Models with numerically sensitive operations — certain recurrent architectures, some normalization variants, and models trained on tasks with extreme output range — can exhibit instability under FP16. BF16 mitigates much of this risk because it preserves FP32's dynamic range. The recommended practice, per PyTorch's official documentation, is to use BF16 on supported hardware (Ampere generation and newer), implement AMP correctly, and monitor gradient norms and loss values during the first few hundred steps to catch instability early.
Q3: How much time does a full GPU utilization optimization pass typically take?
The time required varies with workload complexity and team familiarity with profiling tools — it is not a fixed duration. A focused pass covering profiling, batch size tuning, and AMP enablement on a moderately complex model can be completed in a matter of days by an engineer experienced with the tooling. More involved work, such as custom operator fusion, quantization validation, or distributed training optimization, requires longer iteration cycles. The correct framing is that optimization is ongoing: each infrastructure change — new model architecture, new dataset scale, new serving pattern — warrants a fresh audit.
Final Thoughts
GPU utilization optimization is fundamentally about understanding your workload before spending more on hardware. The most expensive GPU cluster in the world will underperform if the pipeline feeding it is poorly constructed, the batch sizes are arbitrary, or the communication overhead in a distributed setup is unmanaged. The tactics in this guide — profiling at depth, increasing effective batch size, enabling mixed precision, eliminating data pipeline stalls, reducing allocation overhead, applying quantization, and validating multi-GPU efficiency — address the most common sources of preventable waste.
The three points worth carrying forward: measure before you change anything, apply optimizations incrementally so you can isolate their effect, and validate on workloads that reflect production reality rather than benchmarks built for convenience.
Before signing off on an infrastructure expansion, complete at least one thorough optimization audit against your current hardware. The gains are often substantial enough to defer the need for additional compute entirely — and when you do scale, you will scale from an efficient baseline rather than amplifying an inefficient one. If you are at the stage of evaluating what an AI architecture engagement actually entails in practice, the guide on what to expect when you start an AI architecture engagement is a practical next read.
Explore real shipped projects, technical insights, and the professional background behind this work at Darius. Whether you are building something new or scaling what you have, visit the site and get in touch to discuss how end-to-end engineering leadership — from architecture to deployment — can move your project forward.
References
- NVIDIA Corporation. "CUDA C++ Programming Guide and NSight Systems Documentation".
- IEEE. "IEEE Standards and Publications on Distributed Machine Learning and Parallel Computing".
- PyTorch Project (Linux Foundation). "PyTorch Official Documentation: Automatic Mixed Precision and torch.compile".
https://www.linuxfoundation.org
- MLCommons. "MLPerf Training and Inference Benchmarks and Best Practices".
Note: Standards and documentation may be updated; please check the latest official sources or consult qualified engineering advisors before implementation.