
Scaling Machine Learning Models Across Enterprise Teams: A 2026 Playbook
Summary
A comprehensive enterprise ML scaling playbook targeting engineering leaders and CTOs. Covers 7 actionable steps — from model registry to deprecation policies — plus governance, monitoring, and platform team design. Key takeaway: ML scaling success is organizational and architectural, not purely technical.
Details
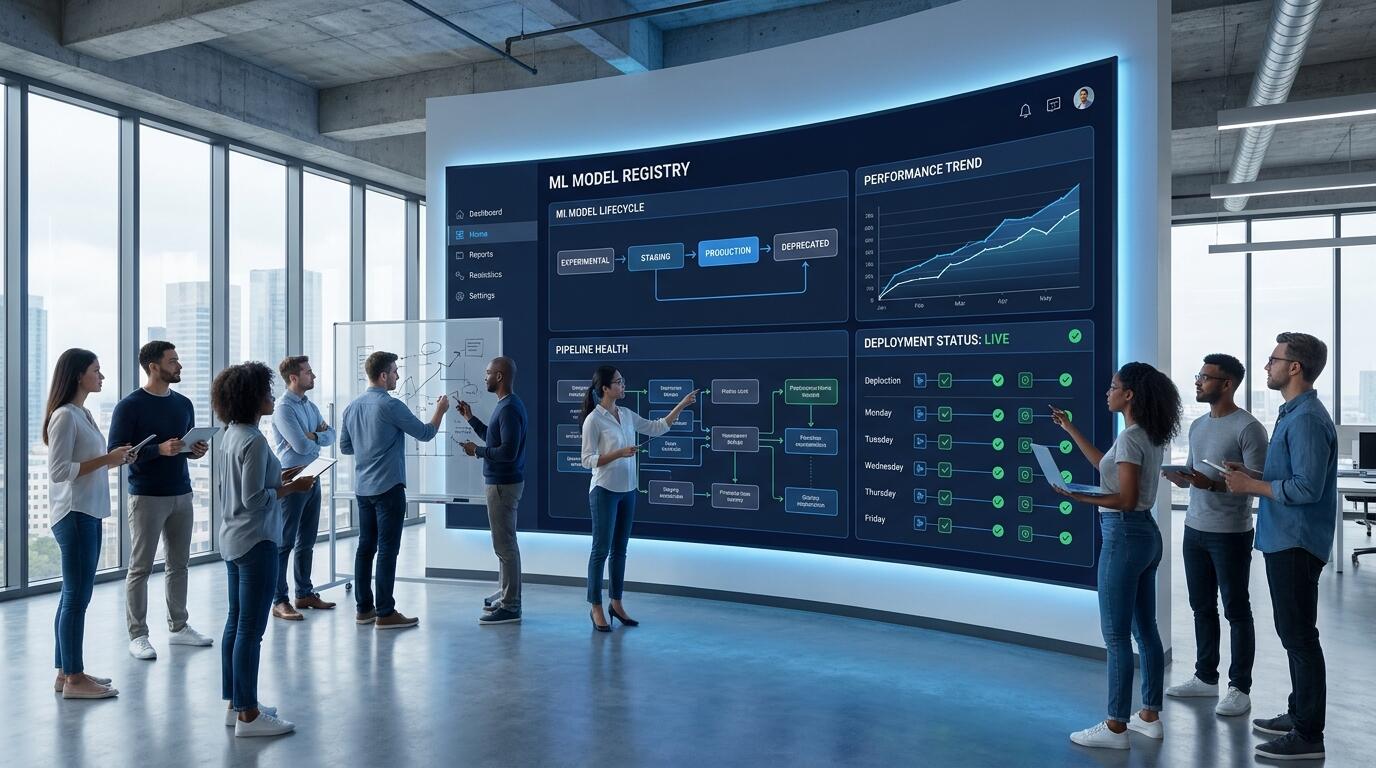 ALT: Engineering teams scaling machine learning models across enterprise organizations in 2026
What Enterprise Teams Actually Need to Scale Machine Learning Successfully
How do you take a machine learning model that performs well in a controlled environment and make it work reliably across dozens of teams, hundreds of users, and multiple production systems — without the whole thing falling apart? That is the question every engineering leader, startup CTO, and product-minded architect is grappling with as AI adoption moves from pilot projects into core business operations.
This playbook is written for technical leaders who are past the "should we use ML?" conversation and are now facing the harder challenge: making ML work at scale, across teams, with real governance, real infrastructure, and real accountability. If you are responsible for shipping AI-powered systems that actually stay alive in production, this guide is for you.
Before You Start: Prerequisites and Preparation for Enterprise ML Scaling
Scaling machine learning across an enterprise is not a single technical project — it is an organizational and architectural program that requires alignment across engineering, product, data, and leadership before a single model is moved closer to production scale. Attempting to scale without this foundation is one of the most consistent patterns we see leading to expensive rework.
Before beginning this process, you need a clear-eyed view of where you currently stand. Most organizations that believe they are "ready to scale" are actually still in a late-prototype phase — their models perform well in notebooks and staging environments but have never been subjected to the load, data drift, team handoff, or compliance scrutiny that enterprise deployment demands.
The preparation phase is not about slowing down. It is about ensuring that the effort you invest in scaling is not wasted on a foundation that cannot hold. Qualitatively, this preparation phase is meaningful work — treat it as such.
Checklist before starting:
- A model or set of models that have demonstrated measurable value in at least one production-adjacent environment
- A defined model registry or version control system for ML artifacts (not just code)
- At least one data pipeline that can be reliably reproduced and monitored
- Organizational alignment on who owns model quality, data quality, and deployment decisions
- A documented risk tolerance and compliance requirement for each model's domain
- Engineering capacity that is not entirely consumed by feature development — scaling ML requires dedicated attention
- A shared vocabulary between data science, engineering, and product teams around what "production-ready" means
- Understanding of your current infrastructure constraints, especially around compute, storage, and access control
 ALT: Engineering director reviewing machine learning infrastructure prerequisites before scaling models across enterprise teams in 2026
How to Scale Machine Learning Models Across Enterprise Teams: Step-by-Step
The following steps represent a sequence that has proven durable across different organizational sizes and industries. They are not strictly waterfall — you will iterate — but the order reflects genuine dependencies. Skipping ahead creates technical debt that is uniquely painful in ML systems because it compounds with data and model drift over time.
Step 1: Establish a Centralized Model Registry and Versioning Standard
The first concrete action in any enterprise ML scaling effort is establishing a centralized model registry — a system that tracks every trained model artifact, its training data lineage, evaluation metrics, and deployment history. Without this, teams independently manage models in ways that are incompatible, unauditable, and impossible to govern.
A model registry is more than a storage solution; it is the source of truth for what is running in production and why it was approved to run there. Platforms such as MLflow and the model registry capabilities built into cloud-native ML platforms can serve this purpose, but the choice of tooling matters less than the discipline of adopting it consistently across all teams.
Versioning standards must cover not just the model file but the training configuration, the dataset version used, and the evaluation threshold required for promotion. When a new model version underperforms in production, you need to be able to roll back with confidence — and that is only possible if the previous version is registered, documented, and reproducible.
Tip: Define a model lifecycle with explicit stages — experimental, staging, production, deprecated — and enforce that no model moves between stages without a documented review. This becomes your audit trail and your operational safety net simultaneously.
Step 2: Build Standardized ML Pipelines That Teams Can Own Independently
Scaling machine learning across multiple teams requires that each team can operate their segment of the ML lifecycle without creating a bottleneck on a central platform team. The way you achieve this without losing consistency is through standardized, reusable pipeline components that teams assemble rather than build from scratch.
A well-structured machine learning pipeline that scales past the prototype stage treats data ingestion, feature engineering, training, evaluation, and deployment as discrete, tested, composable units. Each unit has a defined interface and a defined owner. This means a data science team can swap out their feature engineering logic without breaking the downstream training job, and a platform team can upgrade the deployment infrastructure without requiring every model to be retrained.
In practice, this means investing in pipeline templates and shared libraries before you invest in scaling individual models. The upfront cost feels slow; the downstream benefit is that every new model your organization builds is immediately closer to production-ready because it inherits a tested foundation.
Tip: Avoid the pattern where each data science team writes their own ingestion and preprocessing code. Shared preprocessing creates shared accountability for data quality — and that accountability is what makes enterprise-scale governance tractable.
Step 3: Implement Robust Monitoring and Observability for Every Deployed Model
Model monitoring is the discipline of tracking model behavior in production over time — specifically detecting data drift, concept drift, prediction quality degradation, and infrastructure-level performance issues. According to research from Stanford's Digital Economy Lab, one of the most consistent failure modes in enterprise AI deployment is the absence of systematic monitoring after initial launch.
Every model that is promoted to production must have a defined set of monitoring signals attached to it before it goes live, not after a problem is observed. These signals fall into three categories: data quality metrics (are the inputs still representative of the training distribution?), model performance metrics (are predictions still aligned with ground-truth outcomes?), and operational metrics (latency, throughput, error rates).
The organizational challenge here is deciding who is responsible for acting on monitoring alerts. In our experience working across AI architecture engagements, the most reliable answer is a shared responsibility model: the data science team owns model performance signals, the ML platform team owns infrastructure signals, and a designated ML operations role owns the escalation process. Without clear ownership, monitoring alerts become noise that everyone ignores.
Tip: Do not wait for ground-truth labels to validate model performance. Proxy metrics — measures that correlate with model quality without requiring labeled outcomes — allow you to detect degradation earlier and respond before business impact is significant.
Step 4: Design a Governance Framework That Scales With Your Team Structure
Enterprise ML governance is the set of policies, processes, and controls that determine how models are built, approved, deployed, monitored, and retired. Governance is not a bureaucratic overhead — it is the mechanism by which organizations maintain trust in their AI systems as those systems multiply and evolve.
A governance framework for enterprise ML scaling must address at minimum: model approval workflows, data access controls, explainability requirements by model type and domain, bias and fairness evaluation criteria, and incident response procedures. The appropriate rigor for each of these dimensions varies by domain — a demand forecasting model and a credit-risk model require very different levels of scrutiny.
One pattern we consistently see cause problems is treating governance as a compliance checkbox rather than an engineering design constraint. When governance is bolted on at the end, it slows deployment and breeds resentment. When it is designed into the pipeline from the beginning — as evaluation gates, automated fairness checks, and required documentation fields in the model registry — it becomes a quality driver rather than a bottleneck.
This is also where the build-versus-buy question becomes consequential. Understanding the framework for AI infrastructure decisions in 2026 helps organizations avoid over-engineering custom governance tooling when proven platforms already solve the core problem.
Tip: Define your governance requirements by model risk tier at the start of the program. Low-risk models with limited business impact can move through a lightweight review; high-risk models affecting consequential decisions need a full approval chain. Tiering prevents governance from becoming a one-size-fits-all bottleneck.
Step 5: Create a Cross-Functional ML Platform Team
The organizational architecture of your ML scaling effort is as important as the technical architecture. A cross-functional ML platform team — sometimes called an ML Center of Excellence or an AI Platform team — is a dedicated group responsible for the shared infrastructure, tooling standards, and operational practices that all model-owning teams use.
This team is distinct from the data science or product teams building models. Their job is to make every other team faster and safer by maintaining the centralized model registry, the standardized pipeline libraries, the monitoring infrastructure, and the governance tooling. They are an internal product team whose customers are the ML practitioners across the organization.
The size and formal structure of this team should match organizational scale. For smaller organizations, this might be two or three engineers who maintain shared tooling part-time alongside other responsibilities. For larger enterprises, it becomes a dedicated function with a roadmap and service-level agreements.
Tip: Measure the ML platform team by the velocity and quality of the teams they support, not by the features they ship. If model-owning teams are shipping production models faster and with fewer incidents over time, the platform team is succeeding — even if they have not built anything visibly new in a quarter.
Step 6: Standardize Feature Engineering and Promote a Shared Feature Store
A feature store is a centralized system for storing, sharing, and serving the engineered features that ML models consume. It is one of the highest-leverage investments an organization can make when scaling ML across multiple teams, because it eliminates the most common source of training-serving skew — the gap between how features are computed in model training versus how they are computed in production.
Without a shared feature store, different teams independently compute similar features with subtly different logic. This creates inconsistency across models, wastes engineering effort, and makes cross-model analysis nearly impossible. A well-implemented feature store makes features a first-class organizational asset: discoverable, versioned, monitored, and reusable.
The governance implications extend here too — a shared feature store makes it straightforward to understand which models depend on which data sources, enabling faster impact analysis when upstream data changes.
Tip: Do not attempt to build a feature store from scratch unless you have both the engineering capacity and a clear set of requirements that commercial or open-source options cannot meet. The operational burden of maintaining a custom feature store at scale is substantial.
Step 7: Define and Enforce Model Deprecation and Retirement Policies
Every model that goes into production will eventually need to come out. In our work across AI architecture engagements, model retirement is consistently the most neglected aspect of enterprise ML scaling — teams invest heavily in deployment and ignore the back end of the lifecycle.
Unretired models accumulate as technical and operational debt. They consume compute resources, generate monitoring noise, and create confusion about which model is authoritative for a given use case. More dangerously, they can continue making decisions in production long after the data distribution has shifted beyond the point where their predictions are reliable.
A model deprecation policy defines the conditions under which a model is flagged for review, the review process for deciding whether to retrain, replace, or retire, and the technical procedure for safely removing a model from production without disrupting downstream systems. This policy should be documented in the governance framework and enforced through the model registry lifecycle stages defined in Step 1.
Tip: Treat model retirement as a success, not a failure. A model that ran reliably for its intended lifespan and was cleanly replaced by a better successor is evidence of a mature ML organization, not a sign that the original work was wasted.
Common Mistakes and Troubleshooting in Enterprise ML Scaling
| Symptom | Likely Cause | How to Fix |
|---|---|---|
| Models that perform well in staging degrade quickly in production | Training-serving skew — features are computed differently at training time versus inference time | Implement a shared feature store and enforce consistent feature computation across environments |
| Different teams build similar models with inconsistent results | No centralized model registry or shared pipeline standards; each team operates in isolation | Establish a model registry with enforced lifecycle stages and shared pipeline templates before allowing new model development |
| Governance reviews slow deployments to a standstill | Governance is applied as a manual gate at the end of the pipeline rather than as automated checks throughout | Redesign governance as embedded pipeline checks — automated fairness evaluations, required documentation fields, and tiered risk-based review |
| Monitoring alerts are ignored or generate excessive noise | Too many low-signal alerts without clear ownership or escalation paths | Define monitoring signal tiers by severity, assign explicit ownership for each signal category, and establish a documented escalation procedure |
| Data science teams are blocked waiting on platform infrastructure | ML platform team is understaffed or treating internal teams as low-priority customers | Formalize the ML platform team as an internal product function with service-level agreements and a customer-facing roadmap |
| No one knows which model version is running in production | Versioning was not enforced or the model registry was adopted inconsistently | Conduct a model inventory audit, enforce registry adoption as a deployment gate, and run a retroactive registration exercise for existing production models |
Pro Tips for Better Results When Scaling ML Across Enterprise Teams
Beyond the core steps, a handful of practices separate organizations that scale ML sustainably from those that are perpetually firefighting.
Invest in internal ML education early and continuously. The technical complexity of enterprise ML is not just an infrastructure problem — it is a literacy problem. Product managers who understand feature drift, engineers who can read monitoring dashboards, and executives who understand what model confidence intervals mean are organizational assets. Short, targeted internal workshops for non-ML roles have an outsized return.
Treat data contracts as first-class engineering artifacts. A data contract is a formal agreement between a data producer and a data consumer about the schema, freshness, and quality guarantees of a dataset. When ML models depend on data produced by upstream engineering teams, undocumented assumptions about data quality are a primary failure mode. Making data contracts explicit — and testing them automatically — removes a major category of production incidents.
Design for multi-model architectures from the start. Many enterprise use cases that begin with a single model evolve into systems where multiple models interact — an ensemble, a routing architecture, or a retrieval-augmented generation system. If your pipeline, registry, and monitoring infrastructure are designed around a single-model assumption, the refactoring cost when you need to compose models is high. Think about composability early.
A common misconception worth addressing directly: many technical leaders believe that scaling ML is primarily a model quality problem — that if the model is good enough, the scaling challenges will resolve themselves. In practice, the most capable model is useless if it cannot be deployed reliably, monitored continuously, governed appropriately, and updated safely. The infrastructure, organizational, and governance work described in this playbook is not a prerequisite to doing ML — it is the work of doing ML well at scale.
If you are navigating these decisions and want a structured way to approach your first enterprise AI engagement, understanding what to expect from an AI architecture engagement can help you frame the scope and outcomes correctly from the start.
Questions and Answers
Q1: How do you measure whether an enterprise ML scaling program is succeeding?
Success in enterprise ML scaling is best measured through a combination of velocity and reliability signals: how quickly can a new model move from initial training to production deployment, how often do deployed models experience incidents requiring emergency intervention, and what fraction of models in production have active monitoring with documented owners. Governance maturity, reuse of shared infrastructure, and reduction in duplicate model development across teams are also strong indicators of a scaling program that is working.
Q2: Is a dedicated ML platform team necessary for organizations that are just beginning to scale?
A dedicated ML platform team is not necessary at the earliest stages of scaling, but the function it performs is. Even a single engineer who owns the model registry, maintains shared pipeline templates, and sets versioning standards provides a disproportionate return as the organization's ML footprint grows. The mistake is waiting until the absence of this function has created significant chaos before addressing it — by that point, the remediation cost is substantially higher than early investment would have been.
Q3: How long does it realistically take to establish a production-grade enterprise ML scaling foundation?
The timeline for establishing a durable ML scaling foundation is highly dependent on organizational size, existing data infrastructure maturity, and engineering capacity dedicated to the effort. Qualitatively, organizations that have aligned leadership, an existing data platform, and committed engineering resources tend to reach a stable foundation meaningfully faster than those building from scratch. The more important variable than calendar time is sequencing — teams that attempt to scale model volume before establishing registry, monitoring, and governance standards consistently incur rework that extends the overall timeline.
The Bottom Line
Scaling machine learning models across enterprise teams in 2026 is fundamentally an organizational and architectural challenge, not just a technical one. The organizations that do it well share three characteristics: they treat the ML lifecycle — from registry to retirement — as a first-class engineering concern; they invest in shared infrastructure and cross-functional platform ownership before scaling model volume; and they build governance into the pipeline rather than applying it as an afterthought.
The three most important actions to take from this playbook are: establish a centralized model registry with enforced lifecycle stages before scaling further; build standardized, composable pipeline templates that team can own and extend independently; and assign explicit ownership for every monitoring signal attached to every production model.
Per the research in Stanford's Digital Economy Lab's Enterprise AI Playbook, the gap between organizations that successfully operationalize AI at scale and those that remain stuck in perpetual pilot mode is almost always an execution and infrastructure gap, not a capability gap. The knowledge exists. The tooling exists. What scales ML is the discipline to apply it systematically.
If you are ready to move from ad hoc ML experiments to a durable, production-grade enterprise ML program, the next step is getting the architecture right before expanding the footprint.
Visit the Darius website to explore shipped projects, AI architecture work, and how an experienced engineering leader can help your organization build ML systems that hold up at scale — not just in demos, but in production.
References and Further Reading
- Stanford Digital Economy Lab. "The Enterprise AI Playbook."
- Golden IT Inc. "Scaling Modern Enterprise Architecture in 2026: A Practical Playbook for AI-Ready Growth."
- RITS Center. "Choosing, Building, and Scaling Language AI in 2026."
- IEEE. IEEE Standards and Publications on Artificial Intelligence and Machine Learning Systems.
- National Institute of Standards and Technology (NIST). AI Risk Management Framework and Related AI Standards.
Note: Standards and research publications may be updated; verify against the latest official documents and consult qualified technical advisors for guidance specific to your organization's context.