
Why LLM Evaluation Scores Keep Shifting on the Same Prompt
Summary
This article explains why LLM evaluation scores are inherently unstable, covering root causes like temperature sampling, prompt sensitivity, context position effects, LLM-as-judge bias, and model version drift. Targeted at AI engineers and product leaders, it delivers actionable guidance: run multi-run benchmarks, pin model versions, and build task-specific eval sets from production data as core engineering practice.
Details
 ALT: LLM evaluation scores shifting on the same prompt, AI model reliability and benchmarking challenges
Why Your LLM Evaluation Scores Keep Moving — and What That Tells You About AI Reliability
LLM evaluation scores shift on the same prompt because large language models are inherently non-deterministic systems — their outputs are shaped by sampling randomness, context sensitivity, and evaluation methodology choices that compound into measurable variance even when nothing about your input changes. If you've run the same benchmark prompt twice and gotten different scores, you've encountered one of the most misunderstood properties of modern AI systems. Understanding why this happens — and what to do about it — is foundational to building production-grade AI products that you can actually trust.
This topic deserves serious analytical attention right now because AI teams across the industry are increasingly making architecture, procurement, and deployment decisions based on evaluation numbers that may be far less stable than they appear. The gap between a benchmark score and real-world behavior is not a curiosity — it is an engineering risk.
The State of LLM Evaluation: A Moving Target
LLM evaluation is the practice of measuring how well a large language model performs on defined tasks, and it has become the primary language through which teams assess, compare, and select AI systems. Today, the evaluation landscape is rich but fragmented. Organizations rely on a mix of automated benchmarks, human rating panels, and increasingly, LLM-as-judge frameworks — where one model evaluates the outputs of another. Each methodology carries its own source of variance, and the proliferation of evaluation approaches has not produced consensus; it has produced noise.
The field has matured rapidly. Standardized benchmarks like MMLU (Massive Multitask Language Understanding), HumanEval, and TruthfulQA were developed by academic research groups to provide reproducible comparisons across models. These benchmarks were valuable precisely because they offered structured, repeatable inputs with known expected outputs. Yet even on these carefully designed suites, model scores fluctuate — sometimes across evaluation runs on the same day, sometimes across different infrastructure configurations, and sometimes simply due to changes in how the prompts are formatted.
The broader industry has responded with a proliferation of leaderboards, red-teaming frameworks, and proprietary internal evals. According to the Stanford Human-Centered AI Institute, which publishes the AI Index Report tracking the state of AI development annually, the number of evaluation benchmarks introduced each year has grown substantially — but coverage and rigor vary enormously. A leaderboard score is not a controlled laboratory measurement; it is a snapshot taken under specific conditions that may not replicate in your environment.
In practice — and this is a pattern we consistently see in architectural work with teams building AI-powered products — engineers and product leaders treat evaluation scores as if they were hardware specifications: fixed, reproducible, comparable. That assumption is incorrect, and it leads to real downstream problems: selecting models that underperform in production, building pipelines around reliability assumptions that don't hold, and failing to budget appropriately for the variance management that serious deployment requires.
The Root Causes: Why Scores Never Fully Stabilize
LLM evaluation score instability is not a single bug — it is the aggregate effect of several interacting mechanisms. Breaking these down individually is the first step toward engineering around them.
Temperature and Sampling Randomness
Temperature is a parameter that controls the randomness of a model's token selection during inference. At temperature zero, a model becomes deterministic — it always selects the highest-probability next token. At any temperature above zero, outputs are sampled from a probability distribution, meaning the same prompt can generate different responses on every call. Most production deployments and many evaluation frameworks do not run at temperature zero, because doing so produces brittle, stilted outputs that perform poorly on open-ended tasks. The practical result is that evaluation scores computed over a sample of outputs contain sampling variance by construction. Running a benchmark ten times at a non-zero temperature will yield ten slightly different score distributions, and the mean of those distributions will itself vary with sample size.
Prompt Sensitivity and Format Brittleness
Prompt sensitivity refers to the degree to which a model's output quality changes in response to surface-level variations in how a question is phrased — changes that should, in principle, be semantically irrelevant. Research published by academic groups at institutions including MIT and Stanford has documented that altering punctuation, capitalization, the order of options in a multiple-choice question, or even the presence of a trailing newline character can shift model accuracy by meaningful margins. This means that evaluation scores are entangled with prompt implementation details. Two teams benchmarking the same model on ostensibly the same task but using slightly different prompt templates will produce scores that are not directly comparable.
Context Window State and Token Positioning
Context window position effects arise because transformer-based language models do not treat all tokens in their context window equally. The phenomenon commonly called "lost in the middle" — documented in research from the University of California — describes how models tend to perform better on information placed at the beginning or end of a long context than information buried in the middle. When evaluation prompts are embedded within longer system prompts, few-shot examples, or conversation histories, the effective position of key information shifts, and evaluation scores shift with it. This is particularly relevant for teams evaluating models in realistic multi-turn or retrieval-augmented configurations.
LLM-as-Judge Variance
LLM-as-judge evaluation is a methodology in which a second language model scores the outputs of the model under evaluation, typically using a rubric provided in the judge's system prompt. This approach has become popular because it scales more cheaply than human annotation. However, it introduces a second source of non-determinism: the judge model itself is subject to sampling variance, prompt sensitivity, and its own positional biases. Studies from AI safety research groups have found that judge models exhibit position bias — systematically preferring the first or last response in a comparison pair — and verbosity bias, tending to score longer responses higher regardless of actual quality. Evaluation scores generated by an LLM judge are therefore doubly stochastic.
Infrastructure and Version Drift
Model version drift is a frequently overlooked source of score instability. Cloud-hosted model APIs update their underlying model weights, system prompt defaults, and safety filtering logic on an ongoing basis, sometimes without announcing changes to end users. A benchmark run against GPT-4o or Claude Sonnet today may yield results that differ from a benchmark run against the same named endpoint three months ago — not because your evaluation methodology changed, but because the model did. Teams that build evaluation baselines against API endpoints without pinning to a specific model version are effectively measuring a moving target.
Evidence and Competing Approaches to Evaluation Stability
Score instability on the same prompt is well-documented, though it manifests differently depending on evaluation approach. The challenge is not whether to evaluate — rigorous evaluation is essential — but which combination of methods delivers the most actionable signal given the inherent variance in LLM systems.
When selecting a model or methodology, it helps to understand the trade-offs across the dominant evaluation paradigms in active use:
| Perspective / Approach | Strengths | Trade-offs | Best Fit |
|---|---|---|---|
| Automated static benchmarks (e.g., MMLU, HumanEval) | Reproducible across organizations; widely cited; fast to run | High prompt sensitivity; may not reflect production task distribution; susceptible to benchmark contamination | Cross-model comparison at a point in time |
| Human evaluation panels | High ecological validity; captures nuance and preference | Expensive; slow; inter-rater reliability varies; hard to scale | Qualitative judgment on open-ended generation |
| LLM-as-judge frameworks | Scalable; flexible rubric design; fast iteration | Judge model biases (position, verbosity); double stochasticity; rubric sensitivity | Regression testing at scale when human annotation is cost-prohibitive |
| Task-specific production evals | Directly measures real-world performance; tied to business outcomes | Requires production data and labels; slower to build; harder to generalize | Production deployment validation |
| Ensemble evaluation (multiple methods) | Reduces variance from any single source; more robust signal | Operationally complex; higher cost; requires calibration | High-stakes model selection or architecture decisions |
The honest practitioner's observation is that no single approach eliminates score instability. The teams we see getting the most reliable signal are running ensemble evaluations — combining automated benchmarks with a small human annotation sample and task-specific production evals — and averaging scores across multiple runs to dampen sampling variance. They are also evaluating AI development tools against their specific task distribution before committing to any model or vendor, rather than relying on published leaderboard numbers that were measured under different conditions.
According to IEEE, rigorous software and systems evaluation requires that test conditions closely mirror the operational environment — a principle that applies directly to LLM evaluation but is routinely violated when teams benchmark models on generic suites and then deploy them in specialized domains.
It is also worth noting the contamination problem: models trained on large web corpora may have been exposed to the questions and answers in public benchmarks during training, inflating their scores. This concern has been raised consistently by researchers at institutions including Carnegie Mellon University. A score on a contaminated benchmark is not a measure of generalization — it is closer to a memorization score.
Where LLM Evaluation Is Heading — and What It Means for Your Architecture
The direction of the field is toward more dynamic, task-grounded, and adversarially robust evaluation methods. Static benchmark suites are losing credibility as the primary signal for model quality, and the industry is shifting toward evaluation frameworks that are harder to game and more tightly coupled to real deployment conditions.
Several developments are reshaping how serious engineering teams approach this problem. Automated red-teaming — using adversarial prompt generation to stress-test model behavior — is moving from research into standard practice. Dynamic benchmark generation, where evaluation questions are synthesized fresh rather than drawn from a fixed pool, is emerging as a countermeasure to contamination. And reproducibility standards are gaining traction: the AI research community, including groups affiliated with NeurIPS and academic institutions broadly, is increasingly requiring that evaluation runs report variance across multiple seeds, not just a single point estimate.
For product leaders and engineering teams, the practical implications are concrete:
- Do not make model selection or architecture decisions based on a single evaluation run. Run benchmarks multiple times and report the variance, not just the mean.
- Pin model versions wherever possible. If you are using a cloud API, understand the provider's versioning policy and test explicitly when they announce updates.
- Build task-specific evaluation sets from your own production data as early as possible. The gap between generic benchmark performance and performance on your actual task distribution is often substantial.
- Treat LLM-as-judge scores as directional signals, not ground truth. Use them for regression detection, and calibrate them against human judgments periodically.
- When evaluating end-to-end systems — not just isolated model calls — account for the compounding variance that comes from retrieval, prompt construction, and output parsing stages. Each stage introduces additional variance that accumulates in the final score.
If you are building machine learning pipelines that need to scale reliably past the prototype stage, the evaluation infrastructure is not an afterthought — it is part of the product. Teams that learn this late spend significant engineering time firefighting instability that could have been designed around from the start. Building machine learning pipelines that scale past the prototype stage requires treating evaluation reproducibility as a first-class engineering concern, not a QA checkbox.
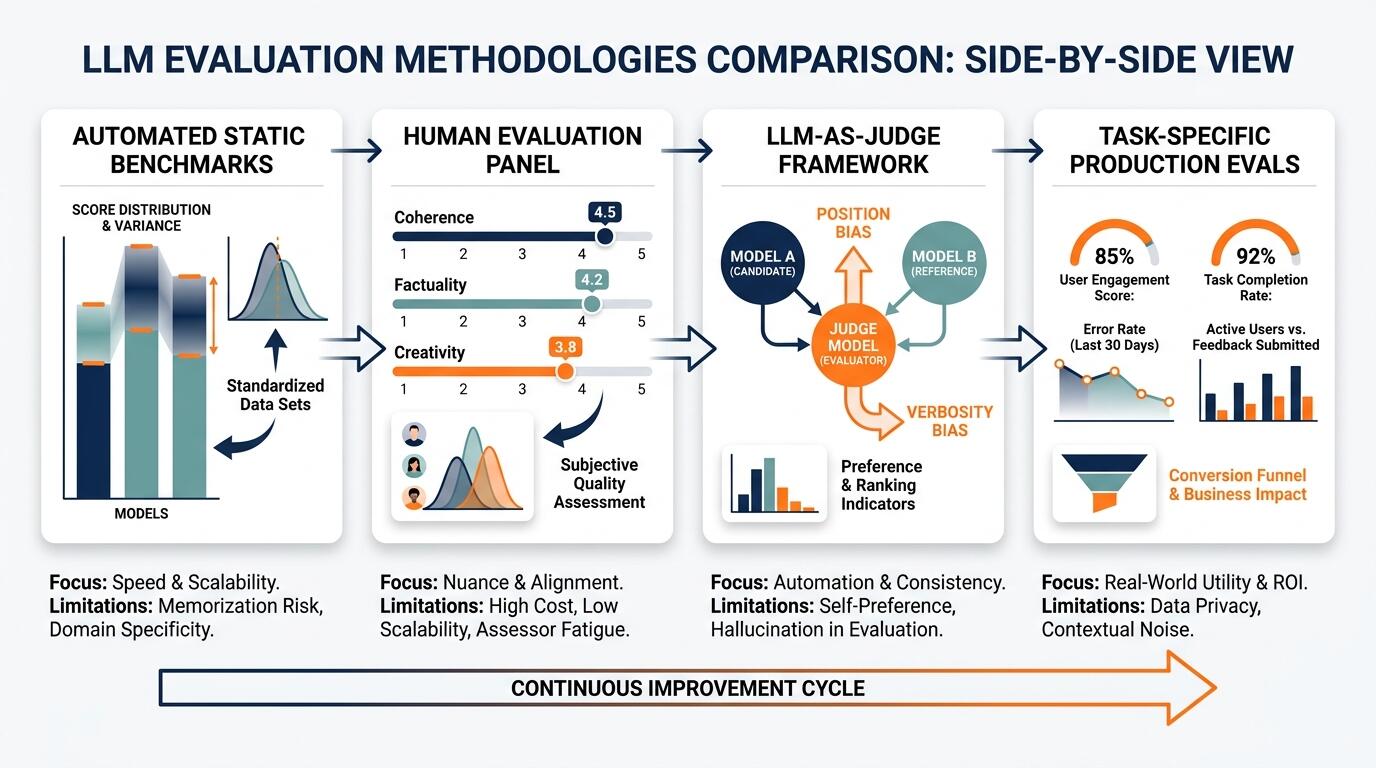 ALT: Comparison of LLM evaluation approaches showing benchmark score variance, LLM-as-judge bias, and prompt sensitivity in AI systems
Common Questions
Q1: How can I make my LLM evaluation scores more reproducible across runs?
Reproducibility in LLM evaluation improves most reliably by reducing stochasticity at each stage. Set temperature to zero for classification and factual tasks where determinism is acceptable. Run every evaluation prompt multiple times and report the mean and standard deviation, not a single result. Use a fixed, version-pinned model endpoint and log the exact prompt template used in each run. Storing evaluation artifacts — prompts, raw outputs, scores — in version control enables meaningful before-and-after comparison as models and pipelines evolve.
Q2: Are published LLM benchmark leaderboard scores reliable for choosing a model for my use case?
Leaderboard scores are a starting point, not a decision. They measure performance under specific benchmark conditions that may differ significantly from your task distribution, prompt style, and context length. Benchmark contamination — where models have been trained on benchmark question-answer pairs — is a documented and ongoing concern raised by researchers at institutions including Carnegie Mellon University. The most reliable approach is to run your own evaluation on a sample of real tasks from your production domain before committing to a model for a significant deployment.
Q3: How long does it take to build a meaningful task-specific evaluation set?
Building a meaningful task-specific evaluation set is an iterative process rather than a one-time effort. A functional starter set — enough to detect regressions and directional quality changes — can typically be assembled in days if you already have production examples and can annotate a sample of them. A robust set that covers edge cases, adversarial inputs, and diverse task variants takes longer, often several weeks of ongoing effort as you collect and label real production data. The investment compounds: a strong evaluation harness pays back its cost on every subsequent model update or architecture change.
Key Takeaways
LLM evaluation score instability is not a measurement error to ignore — it is a structural property of probabilistic systems that every team building on top of language models needs to account for explicitly. Three findings from this analysis stand out as most actionable.
First, score variance has multiple root causes that compound: sampling randomness, prompt formatting sensitivity, context position effects, LLM-as-judge biases, and model version drift all contribute independently and interact in practice. Addressing any single cause without accounting for the others produces only partial improvement.
Second, the evaluation methodology you choose shapes the signal you receive. Automated benchmarks, human panels, and LLM-as-judge frameworks each have structural biases that make them more or less appropriate for different decisions. Ensemble approaches that combine methods and report variance across runs are consistently more trustworthy than single-method, single-run scores.
Third, task-specific evaluation grounded in your production data is the highest-value investment you can make in evaluation infrastructure. Generic benchmark scores are proxies for performance on your actual use case; your own labeled production examples are direct evidence. Building that evaluation harness early — as a first-class engineering artifact — is one of the clearest differentiators between teams that ship reliable AI products and teams that are perpetually surprised by production regressions. For teams thinking through the full scope of what a structured AI engagement involves, understanding what to expect when you start an AI architecture engagement can help frame evaluation infrastructure as part of the broader design conversation from day one.
If your team is navigating model selection, evaluation infrastructure design, or the broader challenge of moving an AI product from promising prototype to production-grade system, the right technical partner makes those decisions faster and more durable. Explore shipped projects, technical insights, and engagement details at the Darius website — and get in touch if you want to work through your evaluation architecture with someone who has built these systems in production.
References
- Stanford University Human-Centered Artificial Intelligence (HAI). "AI Index Report — Tracking the State of Artificial Intelligence".
- IEEE (Institute of Electrical and Electronics Engineers). "IEEE Standards for Software and Systems Engineering — Evaluation and Testing Principles".
- NeurIPS (Conference on Neural Information Processing Systems). "Reproducibility and Evaluation Standards in Machine Learning Research".
- Carnegie Mellon University — Language Technologies Institute. "Benchmark Contamination and Evaluation Integrity in Large Language Model Research".
Note: Standards and research publications may be updated; please check the latest official documents or consult professional advisors.